Training decision trees close to optimality on up to ten million samples.
Overview
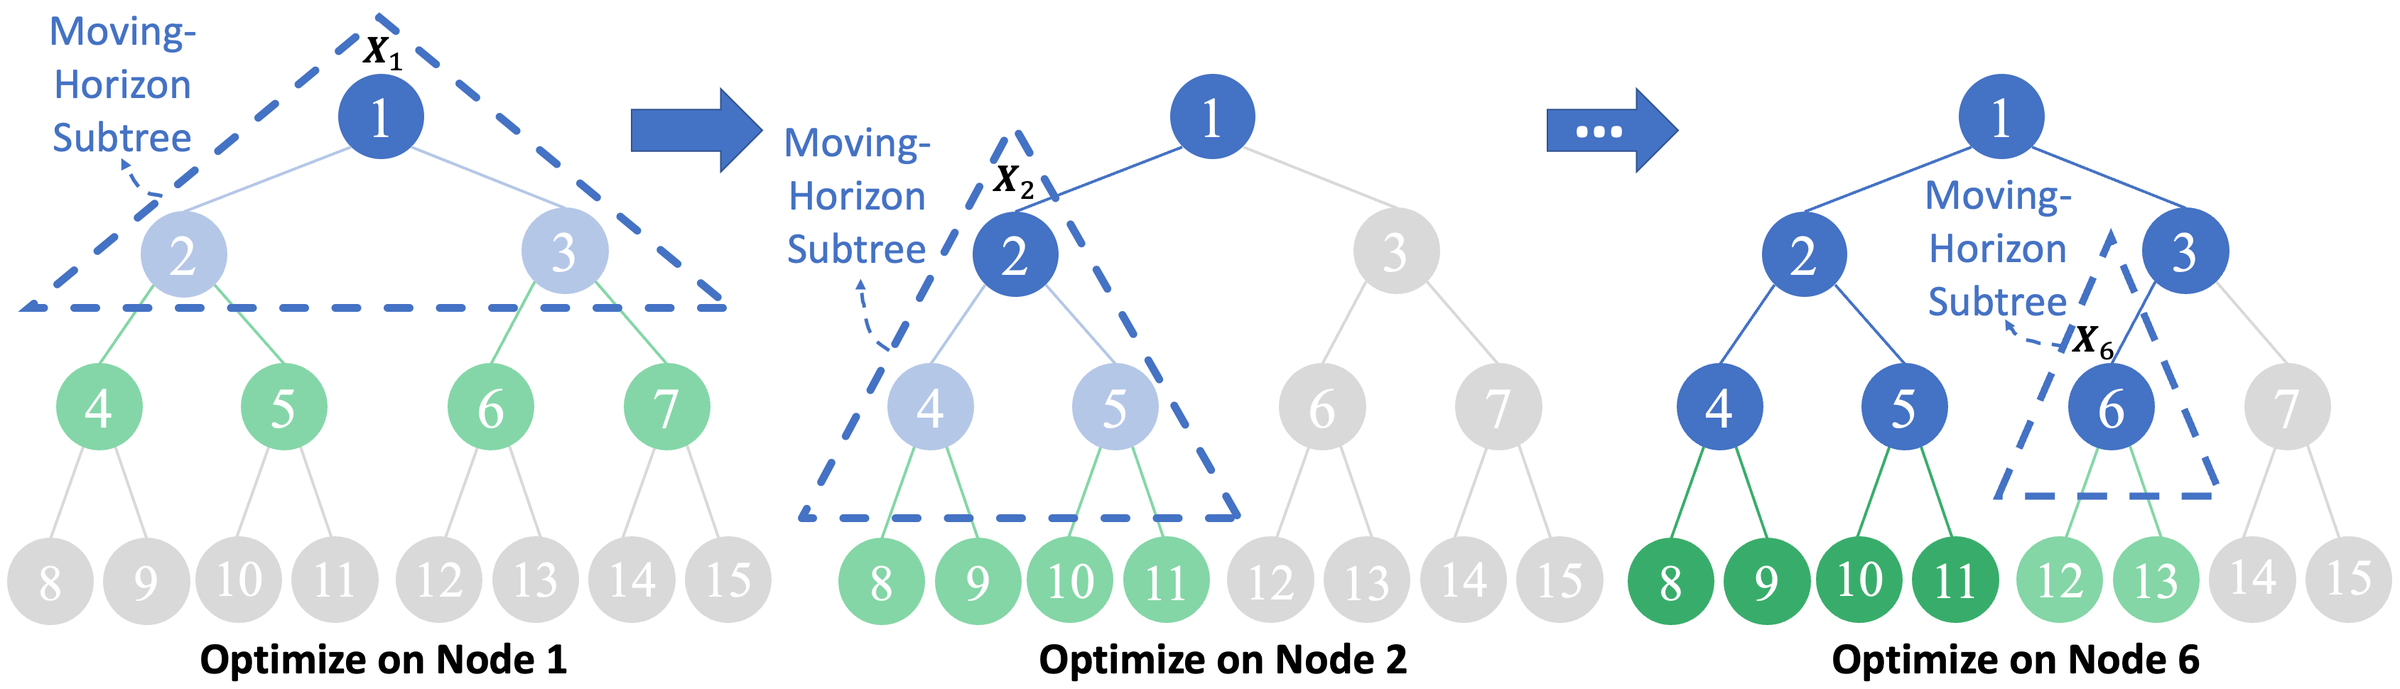
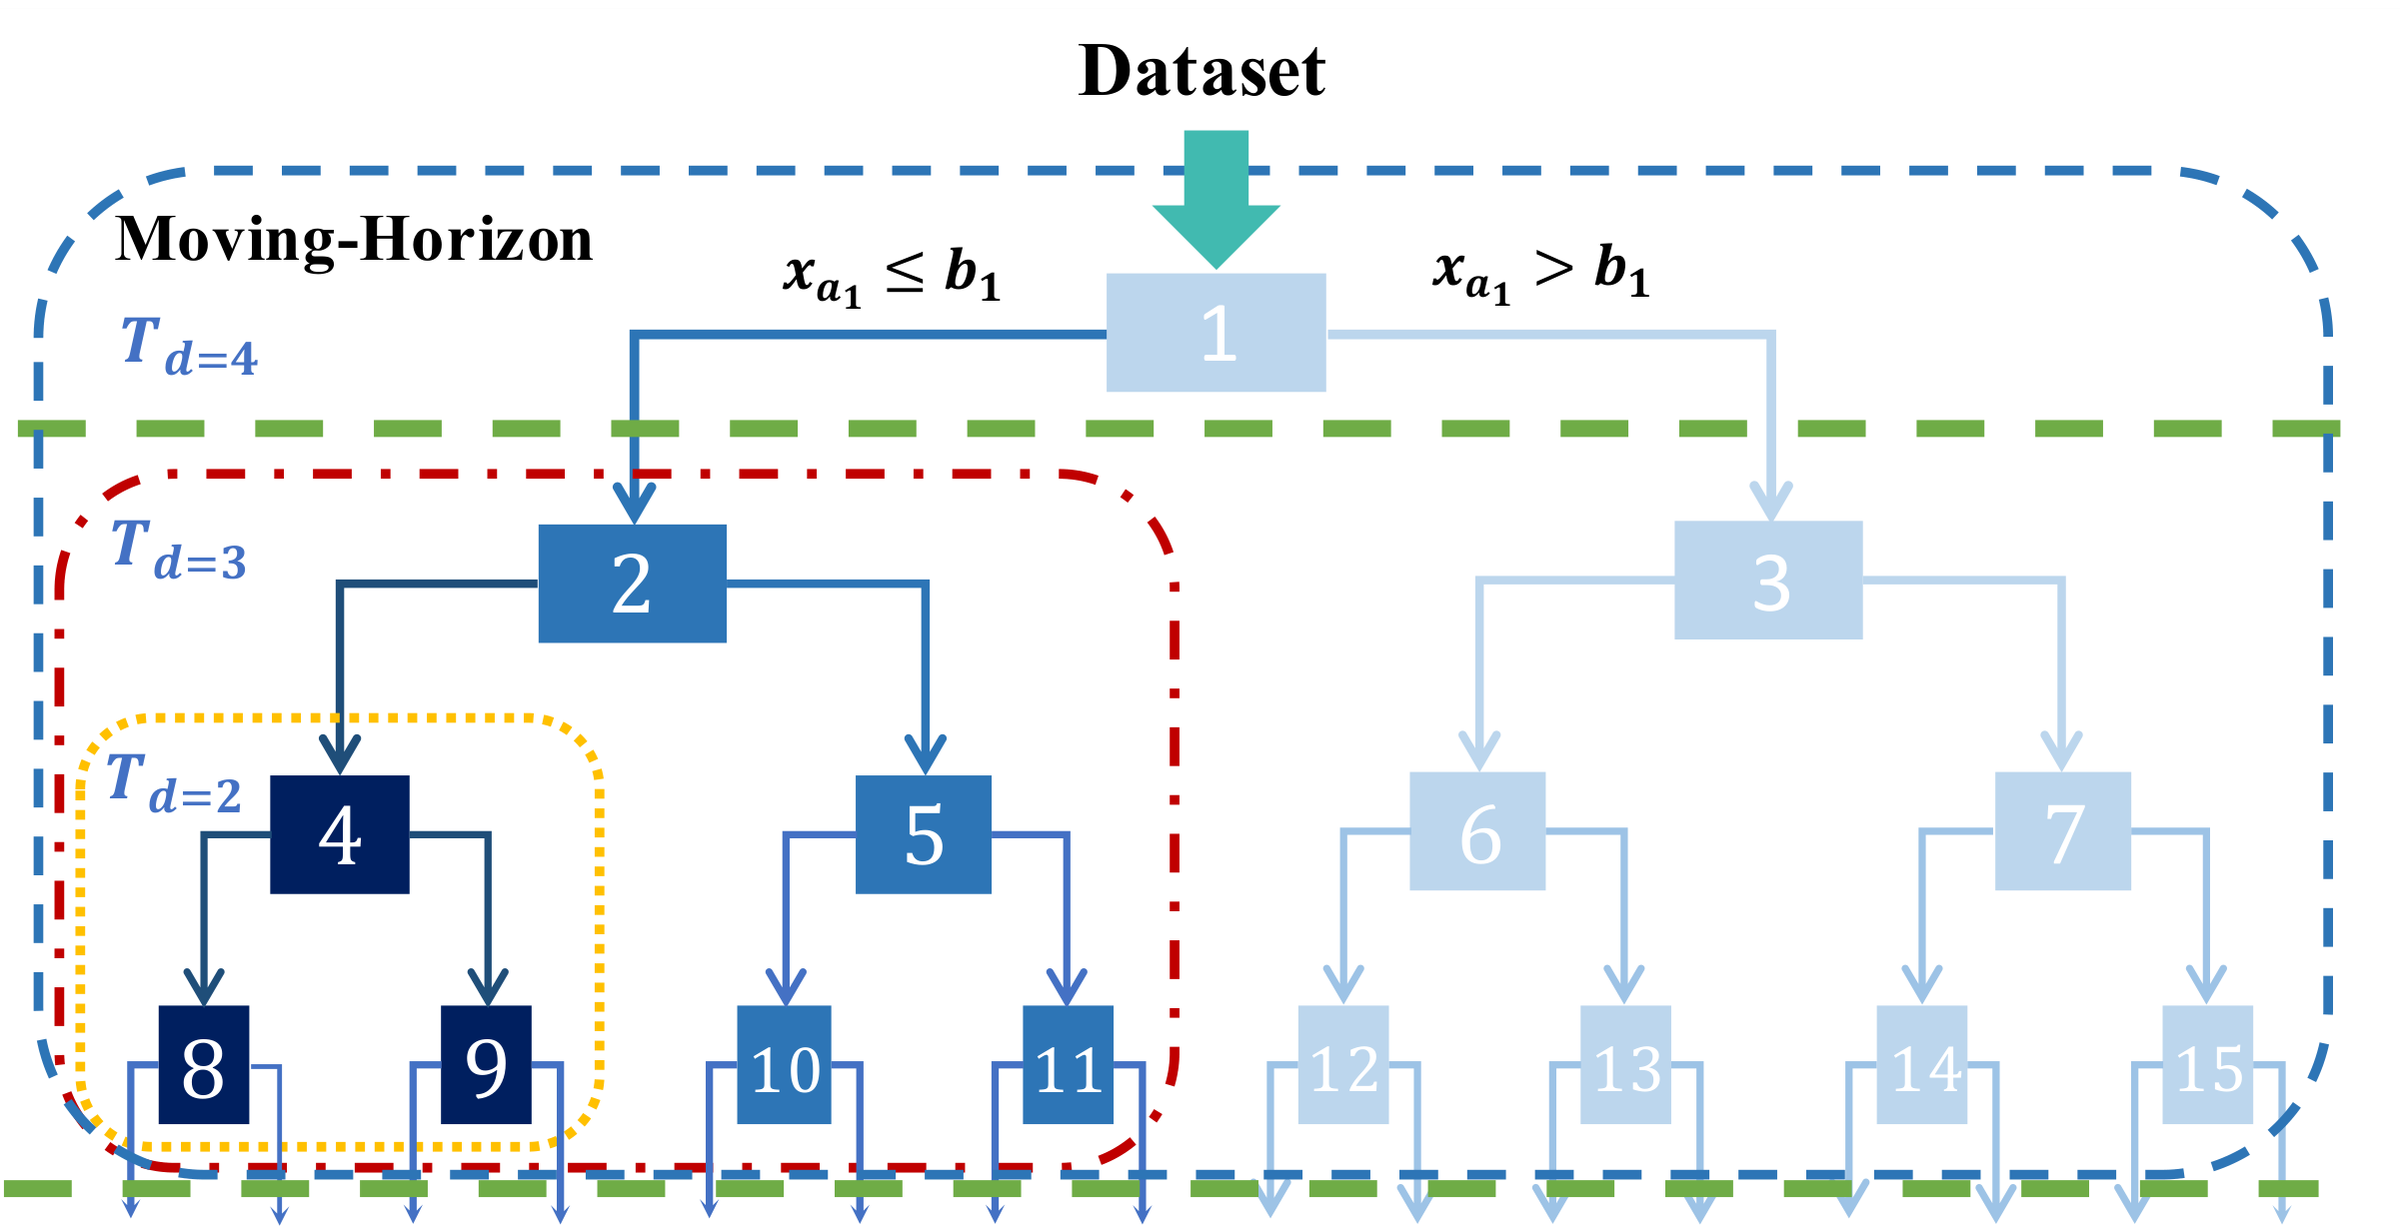
I work on algorithms that train decision trees close to optimality: a scalable deterministic global optimization algorithm for optimal decision trees, GPU-accelerated moving-horizon methods that train deep classification trees on up to ten million samples, and a differentiable “ReLU+Argmin” reformulation of decision trees for gradient-based training.
From the Papers
Code
The moving-horizon method is available as the open-source Julia package MHDETrees.jl (MIT License).
Publications
A Moving-Horizon Approximate Branch-and-Reduce Method for Deep Classification Trees
Transactions on Machine Learning Research (2026).
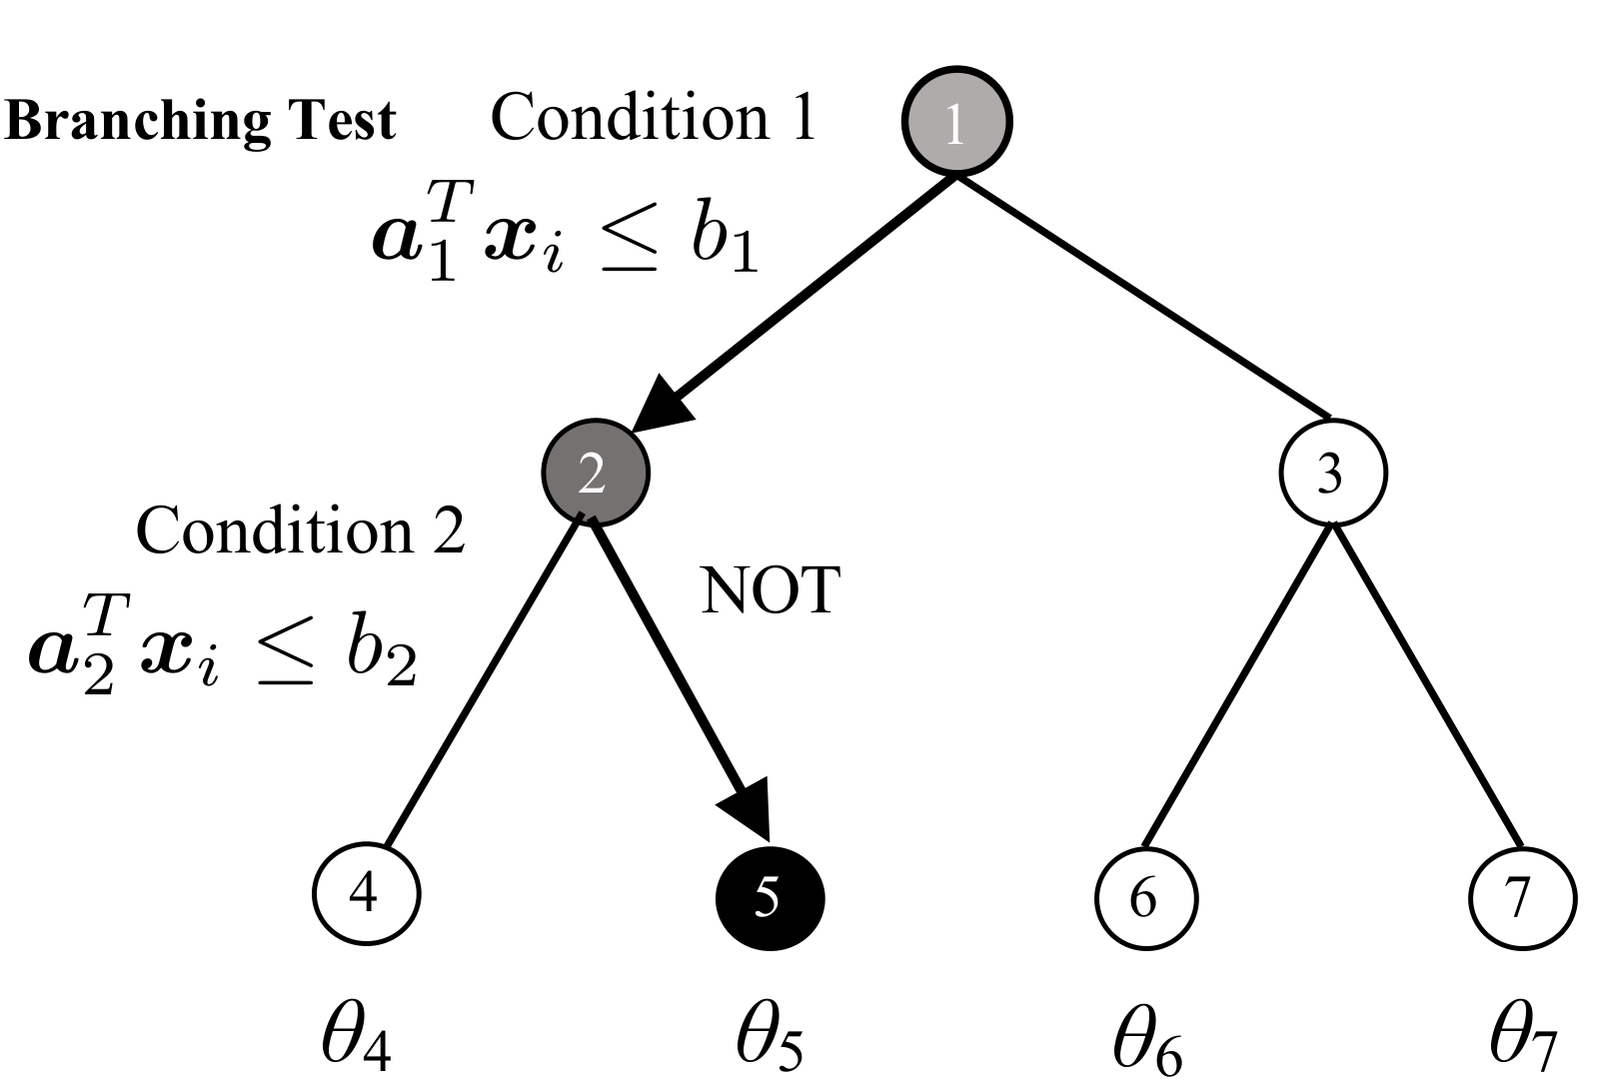
Differentiable Decision Tree via “ReLU+Argmin” Reformulation
Advances in Neural Information Processing Systems, 38: 166874–166909 (2025).
A Scalable Deterministic Global Optimization Algorithm for Training Optimal Decision Tree
Advances in Neural Information Processing Systems, 35: 8347–8359 (2022).
MHDETrees.jl: Moving-Horizon Differential Evolution for Optimal Classification and Regression Trees
Open-source Julia package, MIT License (2026).